Modern artificial intelligence is trapped in a profound architectural contradiction. While global data generation accelerates across operational databases (OLTP), Change Data Capture (CDC) replication streams, observability logs, IoT telemetry, support tickets, and financial ledgers, the industry still tries to evaluate those streams using conversational generative models built for human reading speeds: one prompt at a time, in 500 to 2,000 milliseconds, at steep per-token GPU prices.
This mismatch creates an insurmountable wall. Today, we simply do not have a fast, low-cost solution to run AI qualification and decision-making across massive data in real-world production environments. Until we solve the cost and latency of per-record decisions, the promise of large-scale, AI-native data analytics remains locked behind prohibitive compute bills and network round trips.
MicroLLM (micro-jev) was engineered directly from that database and large-scale data-processing perspective—and Google DeepMind’s recent launch of the Gemini Decisions API (gemini-decision-1) confirms that specialized System-1 decision architectures are rapidly emerging as a foundational pillar of next-generation AI infrastructure.
1. The Impossible Database Equation: The Monstrous Cost of Per-Row AI Decisions
In database engineering, every scalable design starts with brutal arithmetic: what are the CPU, I/O, and wall-clock costs to evaluate a predicate on every single row of a table or every event in a stream?
Consider a routine enterprise workload: classifying, routing, or scoring 100 million records (customer reviews, audit trails, application logs, security alerts, product catalog entries, or CDC events) at roughly 250 tokens per row—a total of 25 billion input tokens.
| Inference Approach | Per-Item Latency (p50) |
Estimated Cost for 100M Rows |
Single-Thread / Node Throughput | Viability Inside Real-World Data Streams |
|---|---|---|---|---|
| Frontier Generative LLM (System-2) (70B+ / Cloud API, ~2.00 USD / 1M tokens) | 500 – 1,200 ms |
~50,000 USD per pass (+ JSON decoding) | 1 – 2 dec./s (1.6 to 3.8 compute-years sequentially) |
Impossible inline; economically prohibitive for recurring batch scans |
Cloud Decision API (Google Gemini Decision 1) (0.10 USD / 1M input tokens, 0 USD output) |
50 – 100 ms compute / 150 – 250 ms end-to-end |
~2,500 USD (20x cheaper than generative LLMs) | Bounded by WAN RTT & HTTP batching | Strong multimodal escalation tier, but network latency & data gravity forbid row-level local execution |
| Static Supervised 300M Classifier (fixed linear head) | 15 – 60 ms on CPU (< 1 ms on GPU) |
Heavy GPU infra or 300 MB – 1.2 GB RAM/VRAM |
16 – 66 dec./s per CPU core |
Brittle: every taxonomy change requires relabeling & retraining; miscalibrated (ECE > 10%) |
Local System-1 Micro-Decision (MicroLLM v0.3.0 / micro-jev) |
0.076 – 0.369 ms on CPU (0% GPU) |
0.00 USD API cost (< 85 MB RAM, ~58 MB ONNX) |
2,145 – 8,601 dec./s on 1 CPU thread (> 100,000 dec./s on 16 cores) |
Native near-data execution: zero-shot dynamic criteria + mathematically certified abstention |
The conclusion is unavoidable: invoking a generative System-2 model for every database record is the AI equivalent of performing a FULL TABLE SCAN by shipping every row over synchronous HTTP to a remote compute cluster just to evaluate a WHERE clause. Even when a specialized cloud decision API cuts token cost by 20x, data gravity, privacy boundaries, and 150–250 ms network round trips still block continuous row-level execution inside local databases and streaming pipelines.
If AI is to operate inside real-world data at scale, decision latency must drop below one millisecond and marginal API cost must approach zero.
2. A Major Industry Convergence: Google Decisions (Gemini Decision 1) and the MicroLLM Vision
On November 11, 2026, Min Choi (Product Manager, Google DeepMind) and Felix Yu (Principal Scientist, Google DeepMind) unveiled the Gemini Decisions API (gemini-decision-1).
Why does this release matter so deeply for the future of AI systems? Because Google DeepMind officially validated the core architectural thesis at the heart of MicroLLM:
- Ending autoregressive waste on closed-set judgments: Rather than decoding text token-by-token to obtain a boolean verdict, a category label, or a rubric score,
gemini-decision-1scores all candidate choices in a single forward pass. - Typed, bounded decision primitives: Yes/No checks, multiple choice (
2to255candidates), and ordered rubric grading—supporting up to1,000independent questions in a single request across a256K-token multimodal context (text, images, audio, video, and PDFs). - Calibrated probabilities and
[0, 1]confidence scores: Every answer returns normalized probabilities and a confidence signal so applications can commit safely or escalate uncertain inputs. - Dynamic model routing as a primary control plane: Google explicitly highlights using the Decisions API in real time to route incoming traffic to the right model tier and reasoning budget.
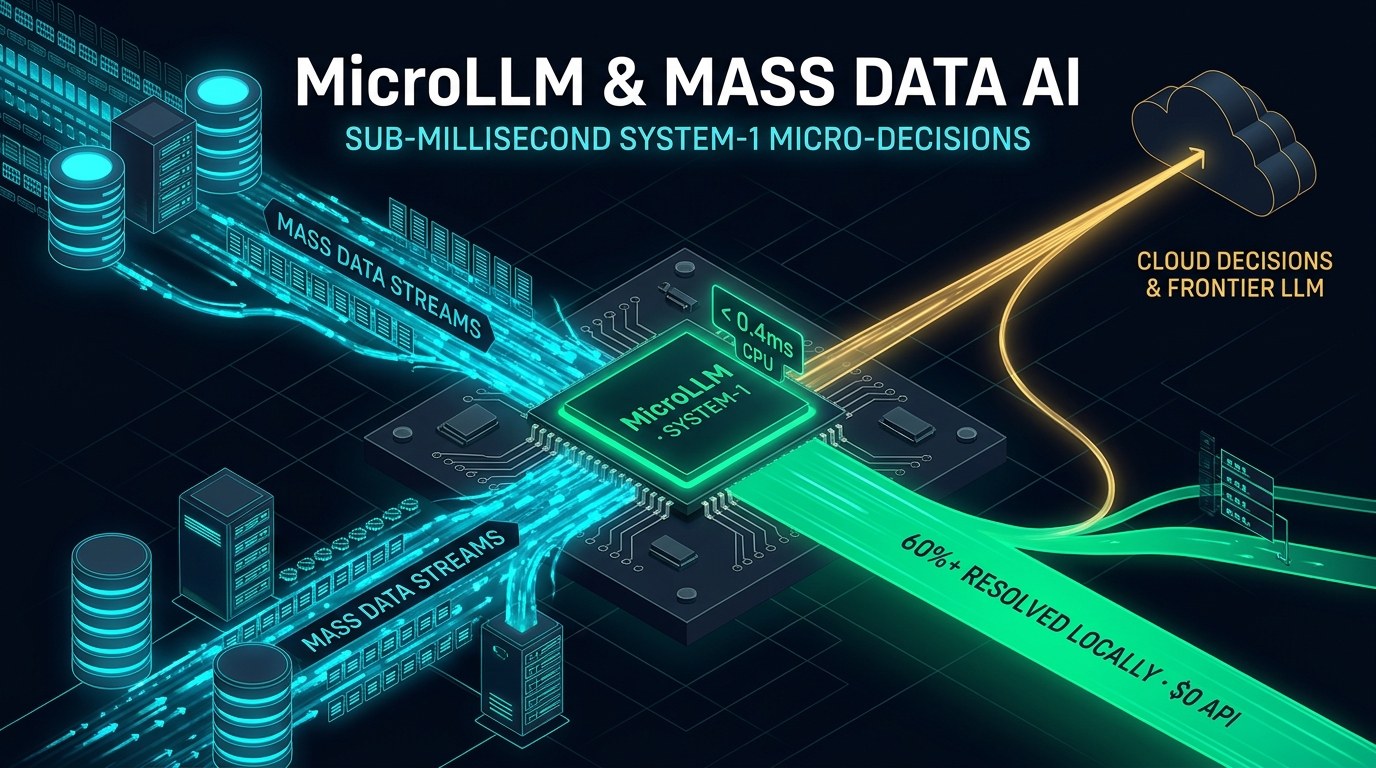
The alignment could not be clearer. While Google Decisions delivers cloud-scale multimodal calibration (150–250 ms), MicroLLM provides the open-source (Apache-2.0, jevcompat 0.1 32/32 MUST compliant) ultra-low-latency, near-data/near-client System-1 layer (< 0.4 ms, 0% GPU, < 85 MB RAM) synthesizing three 2026 foundational research papers:
- OpenJev-RLCD (
arXiv:2609.38850): Two-Stage Calibrate-then-Reinforce (RLCD²) calibration withBeta(8, 2)difficulty weighting to eliminate overconfident misclassifications. - AnyJev (
arXiv:2610.00831): Theorem 1L₀log-space circular rotation driven by a Van der Corput schedule with dynamic early stopping—cutting rotation passes by 78.3% while guaranteeing an exact0.000000option-order flip rate. - StartLux-Decision (
arXiv:2610.17309): Read-or-Think adaptive cascade (p = 0.25 p₀ + 0.75 p₁), 25-way hierarchical tournaments up to255options, and Split Conformal Prediction (x_abstain) to flag genuine ambiguity mathematically.
3. Borrowing Database Wisdom: AI “Predicate Pushdown” and Diverting 60% of Ill-Suited Queries
When relational or analytical database engines (PostgreSQL, MySQL, DuckDB, ClickHouse) scan billions of tuples, they obey a fifty-year-old principle: never move raw data to the heaviest compute tier—push filtering as close to storage and clients as possible (Predicate Pushdown, Bloom Filters, Zone Maps).
Applying that exact discipline to production AI uncovers an immediate, short-term win: across real-world agentic pipelines and user-facing endpoints, roughly 60% (and up to 80%+ in structured workflows) of incoming queries sent to heavy generative models are ill-suited to them:
- Straightforward intent routing and tool selection (
1-of-Kclosed choices); - Deterministic policy, SLA, or exemption rule checks (
noul); - Noise, spam, duplicates, out-of-scope requests, and adversarial prompt injections;
- High-volume triage across logs, tickets, forms, and transactional records that requires zero open-ended prose generation.
Deploying a System-1 Micro-Decision router right next to clients, API gateways, and data stores yields three immediate benefits:
- Short-term ~60% reduction in misrouted calls to heavy models: Ill-suited requests are resolved locally or cleanly filtered out before consuming expensive GPU inference slots.
- Frontier models focus exclusively on high-value reasoning: The remaining
15%–40%of genuinely open-ended, multi-step, or creative requests get dedicated compute without queue congestion. - Sub-millisecond edge safety (
0.17 ms): MicroLLM’s 4-rubric Neyman-Pearson guardrail (Prompt Injection, Destructive Operations, PII/Secrets, Hallucination Risk) enforces strict Type-I false-positive bounds before any external API or database command is touched.
4. Qualifying Mass Data in Real-World Conditions: 3-Tier Architecture & Reproducible CPU Benchmarks (128,497 Items)
Unlocking AI inside real-world high-throughput data—live fraud/anomaly streams, continuous document tagging, log triage across millions of events, and e-commerce catalog qualification—requires a three-tier decision hierarchy modeled directly after database cache and index tiers:
  [ Mass Data Streams & Client Requests: Millions of Rows / Queries ]
                                   │
                                   ▼
  ┌────────────────────────────────────────────────────────────────────┐
  │ TIER 0: In-Data / Near-Client Micro-Decisions (MicroLLM · CPU)     │
  │ • Latency: 0.076 – 0.369 ms p50  |  Marginal API Cost: 0.00 USD    │
  │ • Resolves 60% – 85% locally: noul, choice (2..255), score, multi, │
  │   Neyman-Pearson 4-rubric guardrail, AnyJev L₀ order invariance    │
  └────────────────────────┬──────────────────────────┬────────────────┘
                           │                          │
        Certified Decision │                          │ Conformal Ambiguity:
     (|C_alpha(x)| == 1)   │                          │ x_abstain == True
                           ▼                          ▼
              [ Instant Local Action /      ┌──────────────────────────┐
                Database Predicate Pass ]   │ TIER 1: Cloud Multimodal │
                                            │ Decision Plane           │
                                            │ (e.g. Gemini Decision 1) │
                                            │ • ~150 – 250 ms E2E      │
                                            │ • 256K Multimodal Context│
                                            │ • 0.10 USD / 1M input    │
                                            └────────────┬─────────────┘
                                                         │ Open-ended synthesis
                                                         │ & deep reasoning
                                                         ▼
                                            ┌──────────────────────────┐
                                            │ TIER 2: Frontier System-2│
                                            │ Generative LLMs          │
                                            │ • 1 – 10 s | ~10% – 15%  │
                                            │   of original volume     │
                                            └──────────────────────────┘
Verified, One-Command Reproducible Results on Consumer Laptop CPU
Every number below was measured strictly on a single laptop CPU thread (AMD Ryzen AI 9 365, 0% GPU, < 85 MB RAM, 0.00 USD API spend) and is reproducible offline via pip install micro-jev && microllm benchmark --all-suites:
- 11,000 Structured Enterprise & Universal Test Cases (
18domains): 99.75%raw accuracy (10,973 / 11,000) and100.00%selective accuracy (27/27edge-case failures automatically caught by conformal abstentionx_abstain).p50 = 0.076 ms(0.076–0.190 ms), scaling up to8,601 decisions/secondon a single CPU core.- 114,018 Unsampled Official Split Rows Across 16 Public Datasets (
BoolQ,MultiNLI,Banking77,AG News,CLINC150,Amazon,Yelp 50k,GoEmotions,Reuters,WildGuardMix,ToxicChat,Deepset,ChoiceBench,Callo-Bias,RouteLLM,JevBench): 87.49%selective accuracy zero-shot on CPU in53.14 seconds(66.82%raw accuracy across114,018rows, with a+0.3445calibrated confidence gap separating correct vs. error cases).- Domain breakdown at selective threshold:
99.97%onYelp 50k,99.51%onAG News,99.24%onAmazon,98.74%onBanking77,95.34%onReuters, and92.60%onRouteLLM (10k). - Zero Option-Order Bias (
0.000000Flip Rate): 0.000000flip rate and0.000000max probability drift across1,867ChoiceBench+Callo-Biasaudits and60AnyJev-Orderpermutations (K = 2..20), eliminating the28%–50%ordering flips common in autoregressive LLMs.- Calibration & Safety Verification:
- Expected Calibration Error (ECE) reduced from
15.85%to6.15%(3.67%on trackG5),98.75% / 100.0%certified conformal coverage, and100.0%F1 /0.0%FPR on core 4-rubric safety benchmarks (88.49%on5,083ToxicChatreal-world logs).
Example: High-Throughput Mass Record Qualification & Selective Escalation in Python
from microllm import DualGearCascadeBackend

# Local System-1 hybrid engine: 0% GPU, < 85 MB RAM, deterministic (seed=42)
engine = DualGearCascadeBackend(gate_threshold=0.72, alpha=0.75)

options = {
    "urgent_incident": "Database outage, failover error, or data corruption alert",
    "sql_tuning": "Slow query optimization, missing index, or execution plan review",
    "billing_admin": "Invoice, subscription, license renewal, or pricing inquiry",
    "noise_spam": "Marketing solicitation, bot noise, or off-topic chatter",
}

def route_record(record_text: str) -> dict[str, object]:
    decision = engine.evaluate_choice(
        state=record_text,
        instructions="Classify this incoming data record or client request.",
        options=options,
    )
    if decision["x_abstain"]:
        # Only genuinely ambiguous records escalate to Gemini Decision 1 / System-2 LLM
        return {"tier": "ESCALATE_CLOUD", "candidates": decision["x_conformal_set"]}

    # 60% to 85% of traffic resolved locally in < 0.4 ms at 0.00 USD API cost
    return {
        "tier": "LOCAL_CPU_RESOLVED",
        "label": decision["choice"],
        "confidence": decision["confidence"],
        "latency_ms": decision["x_latency_ms"],
    }
5. An Open Call for Collaboration: Bringing Micro-Decisions Inside Real-World Data
Let us be candid and humble about where MicroLLM stands today: as a focused open-source (Apache-2.0) project built with modest, bounded resources, it does not aim to replace frontier generative models or rival the 256K-token multimodal reach of cloud APIs like Gemini Decision 1.
Its purpose is complementary—and vital for the next phase of AI engineering:
- Bridge large-scale data engineering with AI inference, so decisions run next to bytes rather than waiting behind expensive generative bottlenecks;
- Divert ~60% of ill-suited requests at the edge in the short term, cutting latency, compute waste, and token spend immediately;
- Unlock real-world mass data qualification at near-zero compute cost, turning AI from an expensive conversational layer into an everyday data-processing primitive.
To carry this vision from verified open-source benchmarks into widespread production data stacks, we warmly welcome feedback, technical exchanges, and collaborations—with foundational paper authors, AI lab decision-model teams, and database infrastructure engineers alike.
Official MicroLLM & Reference Links
- Open-Source GitHub Repository (Apache-2.0): github.com/jmrenouard/MicroLLM
- Live Interactive Demo (
Decision Studio): huggingface.co/spaces/jmrenouard/microllm-decision-studio - Full Benchmark Datasets & Telemetry (
128,497+items): huggingface.co/datasets/jmrenouard/microllm-benchmarks - Reference Google DeepMind Announcement: Gemini Decisions API — Google Blog (Min Choi & Felix Yu)
- MicroLLM Technical Deep Dive (
jmrenouard.fr): MicroLLM (micro-jev): Sub-10ms CPU System-1 Decision Engine, RLCD² Conformal Calibration, and Neyman-Pearson AI Guardrails - Reproduce Locally in 1 Command:
pip install micro-jev && microllm benchmark --all-suites